Назад к блогуai-architecture 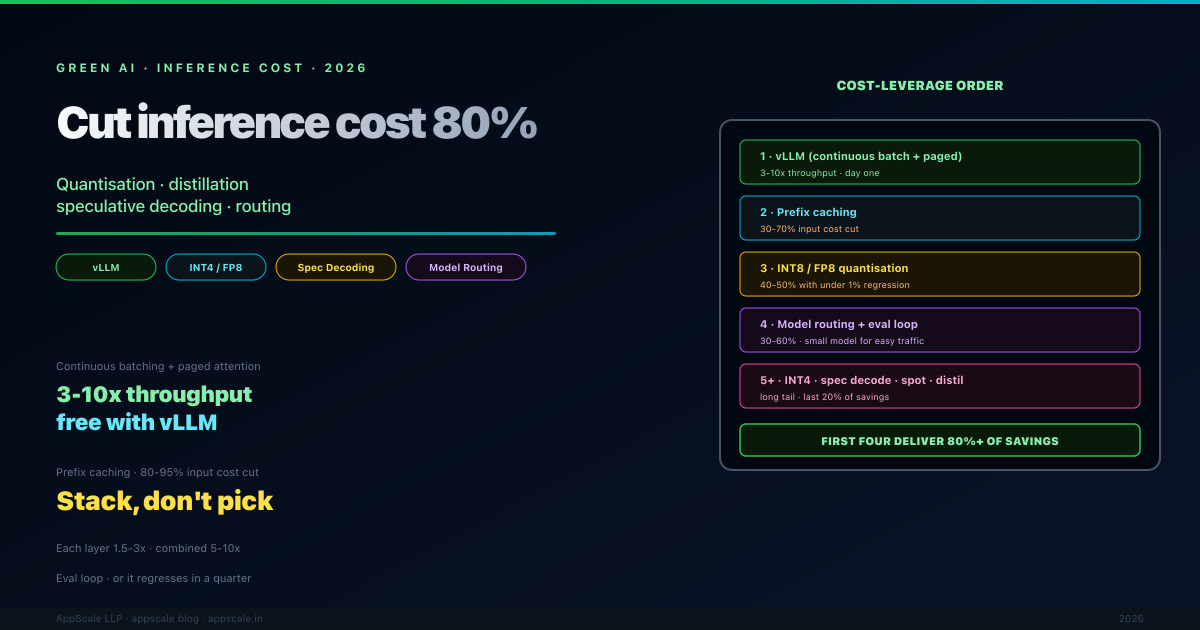
Green AI: Cut Inference Cost 80% with Quantisation, Distillation, Speculative Decoding (2026)
Green AI LLM inference cost quantisation GPTQ AWQ INT4 quantisation INT8 quantisation FP8 speculative decoding EAGLE-2 Medusa distillation continuous batching paged attention vLLM TGI TensorRT-LLM SGLang prefix caching KV cache model routing spot GPU MIG carbon-aware scheduling inference cost optimisation