Skip to content
عودة إلى المدونة
ai-architecture

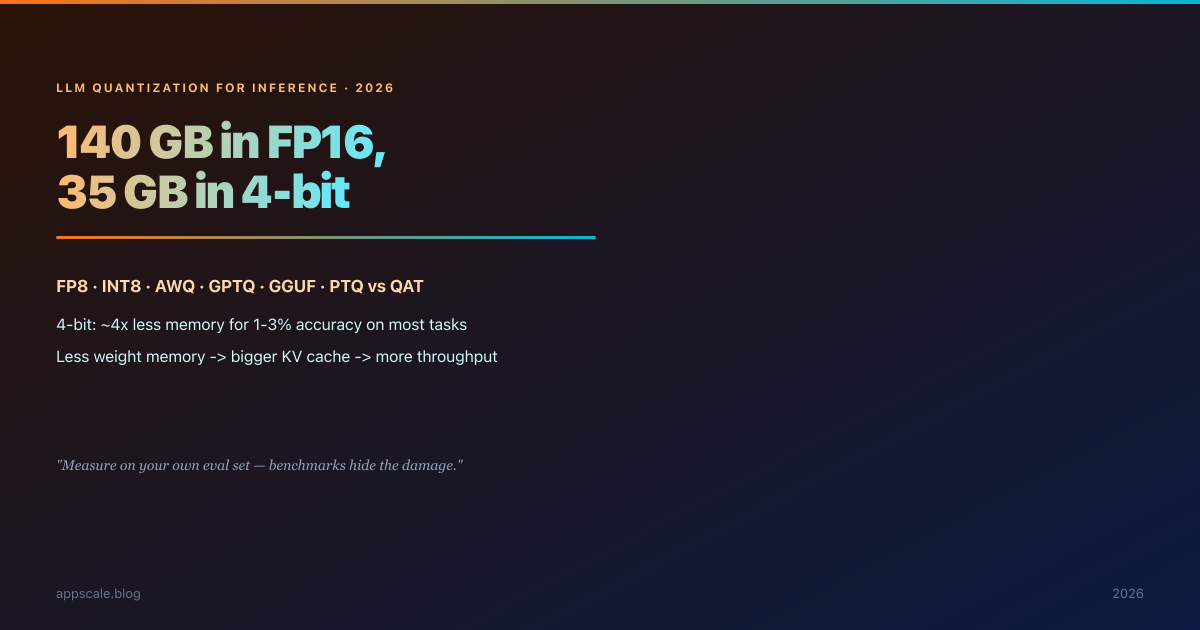
LLM Quantization for Production Inference: INT8, FP8, AWQ, and GGUF

By Satyam KumarJune 28, 20267 min read
llm quantization model quantization int8 quantization fp8 inference awq gptq gguf bitsandbytes post-training quantization quantization-aware training llm inference optimization gpu memory vllm serving open-weight models ai infrastructure cost 2026
LLM Quantization for Production Inference: INT8, FP8, AWQ, and GGUF

Frequently Asked Questions

شارك هذه المقالة

Twitter LinkedIn WhatsApp

Satyam Kumar

Founder & AI Architect, AppScale LLP

مهندس الذكاء الاصطناعي والسحابة. مساعدة الفرق على بناء أنظمة تتسع للملايين.

Comments

Leave a comment