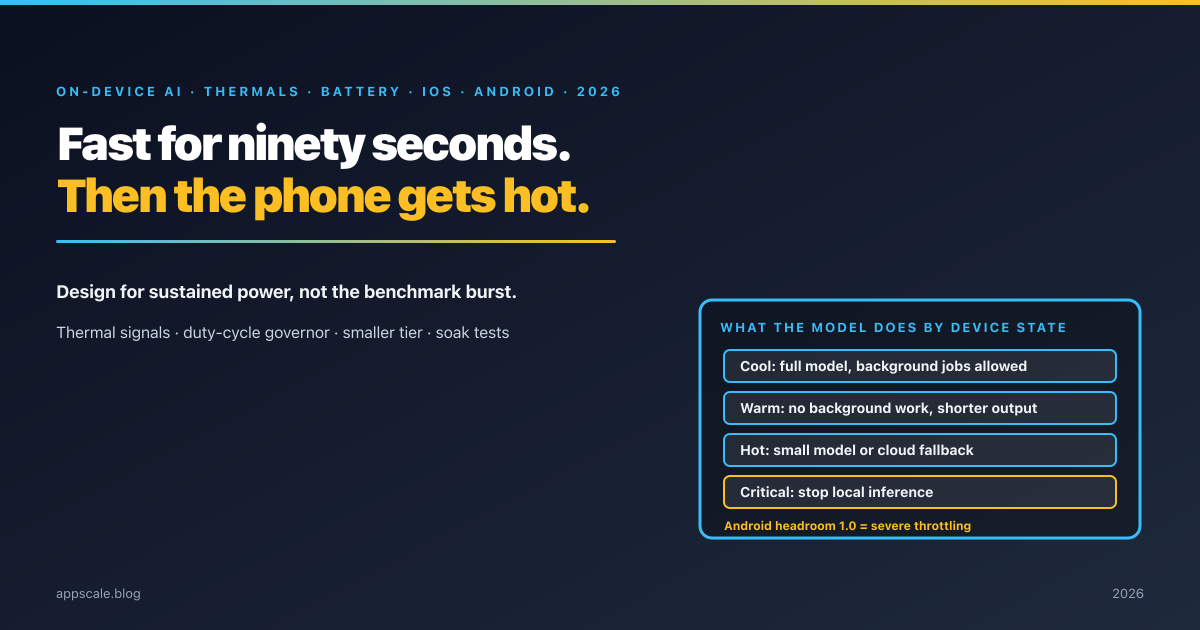
Your On-Device Model Is Fast for Ninety Seconds: Battery and Thermal Budgets for Mobile Inference in 2026


Why on-device model updates turn into full re-downloads, and the 2026 weight layout that keeps them small: frozen base, LoRA adapters, per-file hashes and AI packs.
Memory safety versus bare-metal control for mobile AI engines. Where the three crash classes live, why ecosystem gravity beats safety, and where to put the unsafe seam.
Mobile, PC, console or web? Store cuts, review gates and hardware floors from vendor pages, plus what PawScooty taught us. Pick one platform, then port.
LLMs leak training data through query access alone — membership inference and model inversion. The defence architecture: reduce memorisation, limit the signal.
Advertise and partner
Reach engineering leaders and CTOs reading about AI, mobile and cloud architecture.
Sponsored mentions and co-authored articles or technical deep-dives. Relevant products only, always disclosed.