Zurück zum Blogai-architecture 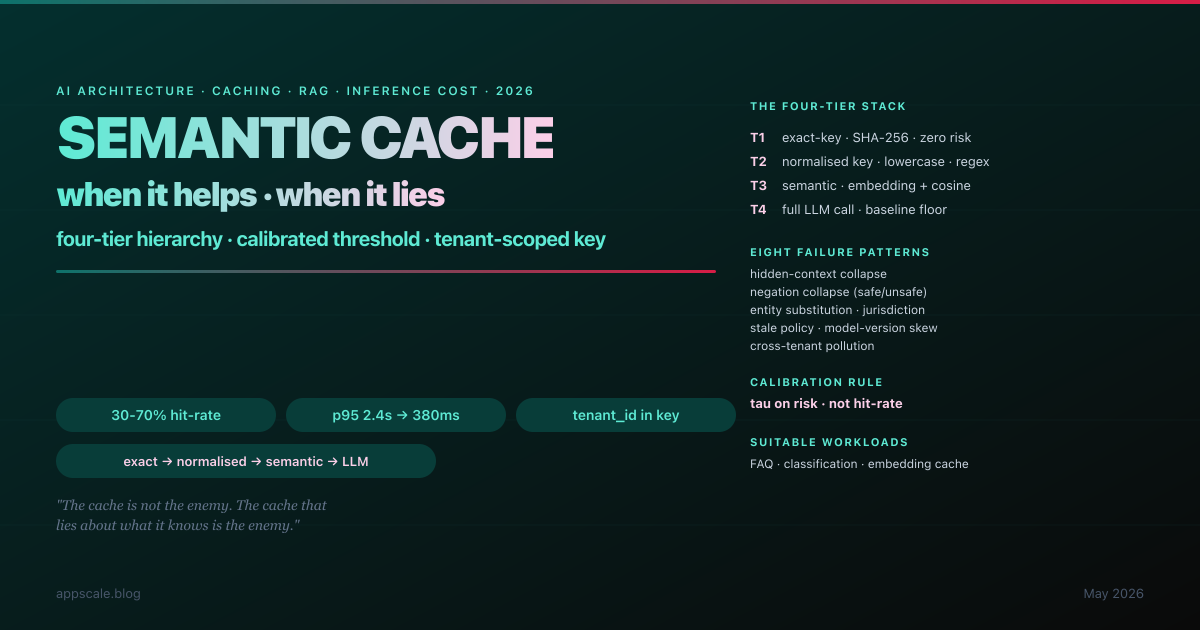
Semantic Cache Pattern: When It Helps, When It Lies — A 2026 Architecture Guide for LLM Features
semantic cache llm cache ai architecture cache hierarchy embedding cache cosine similarity cache calibration multi-tenant cache cache invalidation cache ttl prompt caching rag caching llm cost optimization inference latency p95 latency ai service patterns false positive rate production llm 2026