Skip to content
Zurück zum Blog
ai-architecture

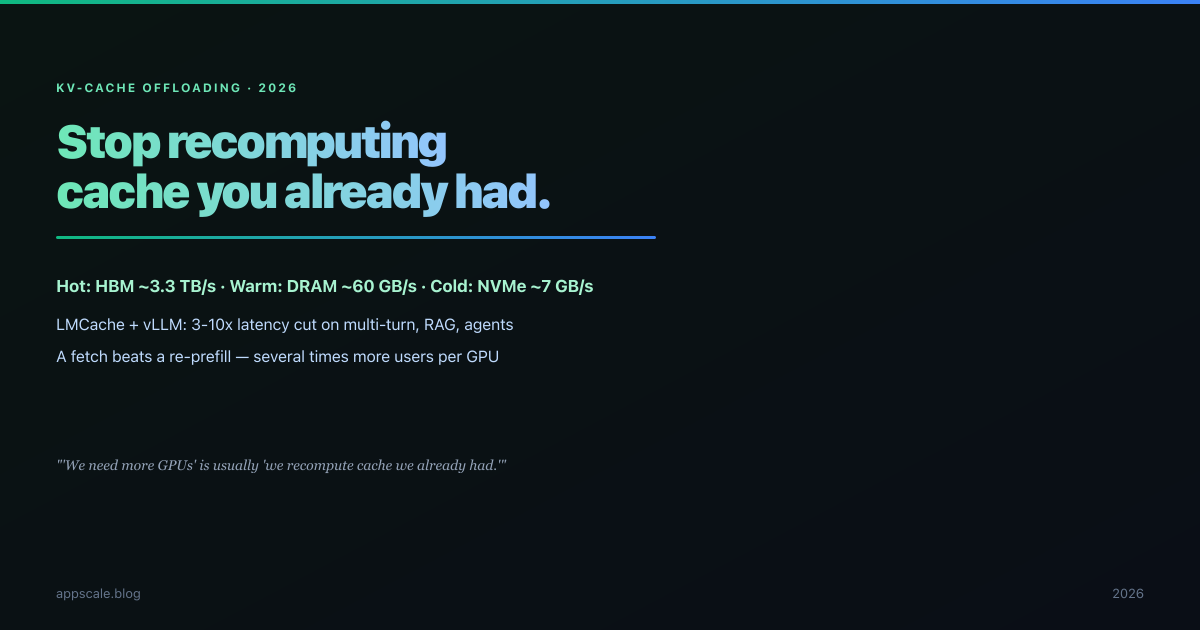
KV-Cache Offloading: Serving 10x More Users by Not Recomputing

By Satyam KumarJuly 13, 20269 min read
kv cache offloading llm inference optimization lmcache tiered memory nvme kv cache cxl memory vllm nvidia dynamo prefix caching gpu memory inference economics prefill recompute multi-turn inference rag serving ai infrastructure llm cost optimization 2026
KV-Cache Offloading: Serving 10x More Users by Not Recomputing

Frequently Asked Questions

Artikel teilen

Twitter LinkedIn WhatsApp

Satyam Kumar

Founder & AI Architect, AppScale LLP

KI & Cloud Architekt. Ich helfe Teams, Systeme zu bauen, die auf Millionen skalieren.

Comments

Leave a comment