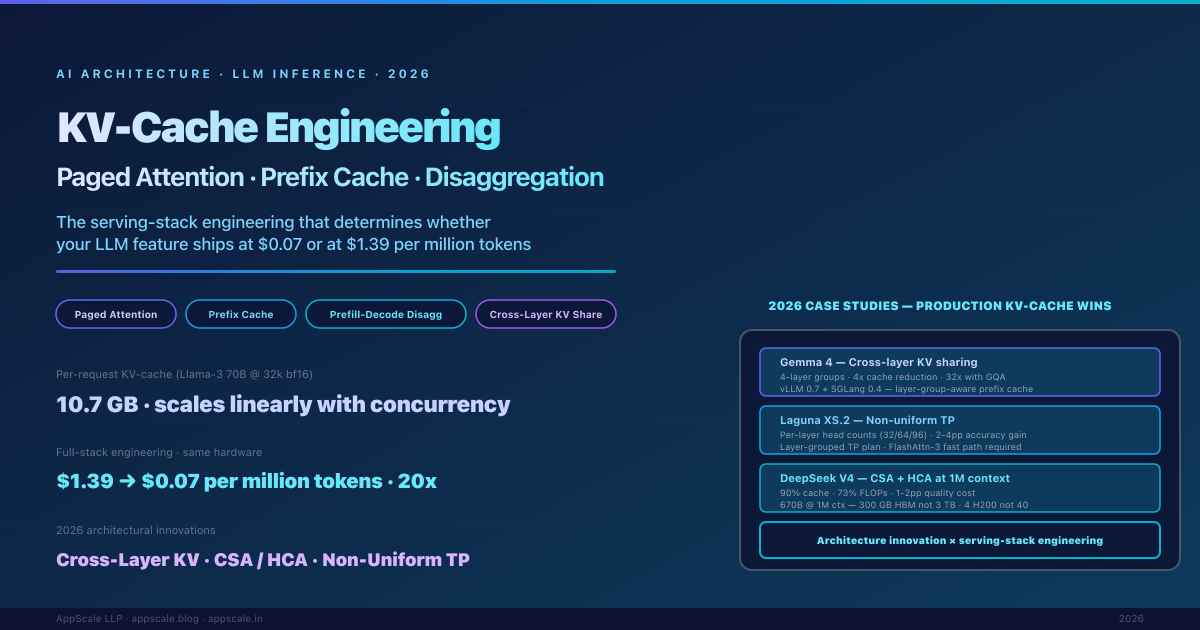
KV-Cache Engineering for LLM Inference: Paged Attention, Prefix Cache, and Prefill/Decode Disaggregation (2026)


vLLM, SGLang or TensorRT-LLM? How to choose an LLM inference server in 2026 by prefix-reuse ratio and hardware commitment, not by a public benchmark.
Your GPU re-prefills the same 15,000-token prompt ten thousand times a day. KV-cache offloading to DRAM and NVMe turns that recompute into a cheap fetch — 10x users.
Production LLM agents fail on cost, latency, and memory when the context window is filled like a bucket. Context engineering treats it as a budget allocated every turn.
GPUs dominate self-hosted inference cost. Quantization cuts memory 2-4x for a small accuracy hit: FP8, INT8, AWQ, GPTQ, GGUF, PTQ vs QAT, and when not to do it.
Advertise and partner
Reach engineering leaders and CTOs reading about AI, mobile and cloud architecture.
Sponsored mentions and co-authored articles or technical deep-dives. Relevant products only, always disclosed.