Back to Blogai-architecture 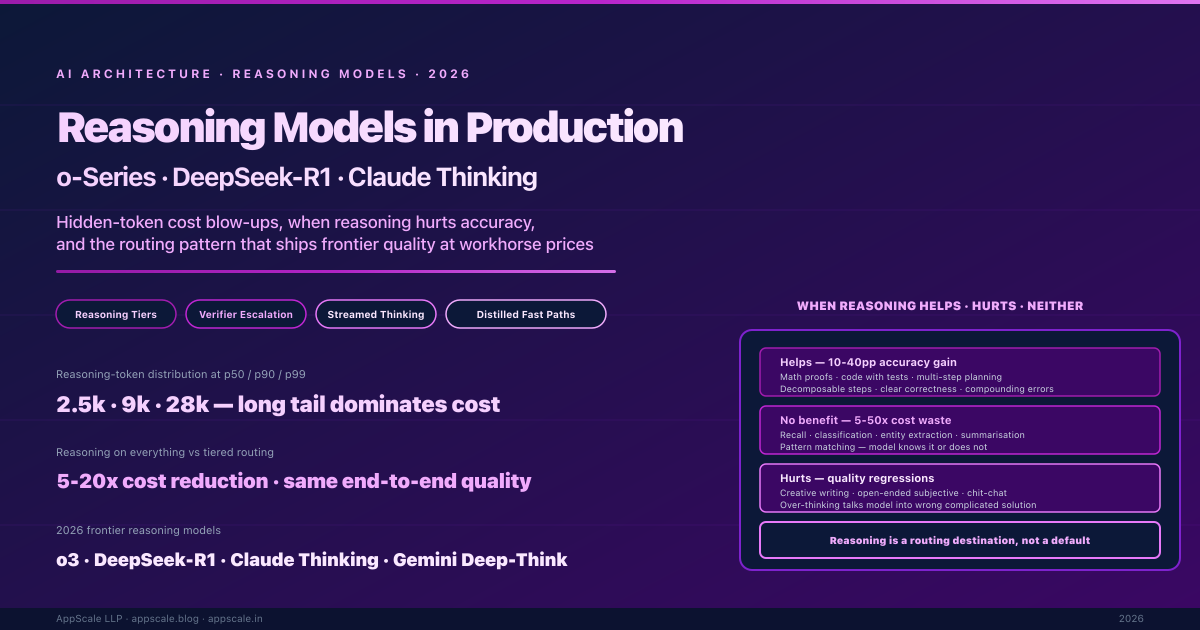
Reasoning LLM Models in Production: o-Series, DeepSeek-R1, Claude Extended Thinking — Architecture, Routing, and Cost (2026)
reasoning llm chain of thought openai o3 o-series deepseek r1 claude extended thinking gemini deep think qwen qwq reasoning model architecture model router llm cost engineering hidden token cost reasoning token verifier escalation model distillation reasoning streaming ux agent reasoning eval harness production llm architecture enterprise ai