Skip to content
Volver al Blog
AI Architecture

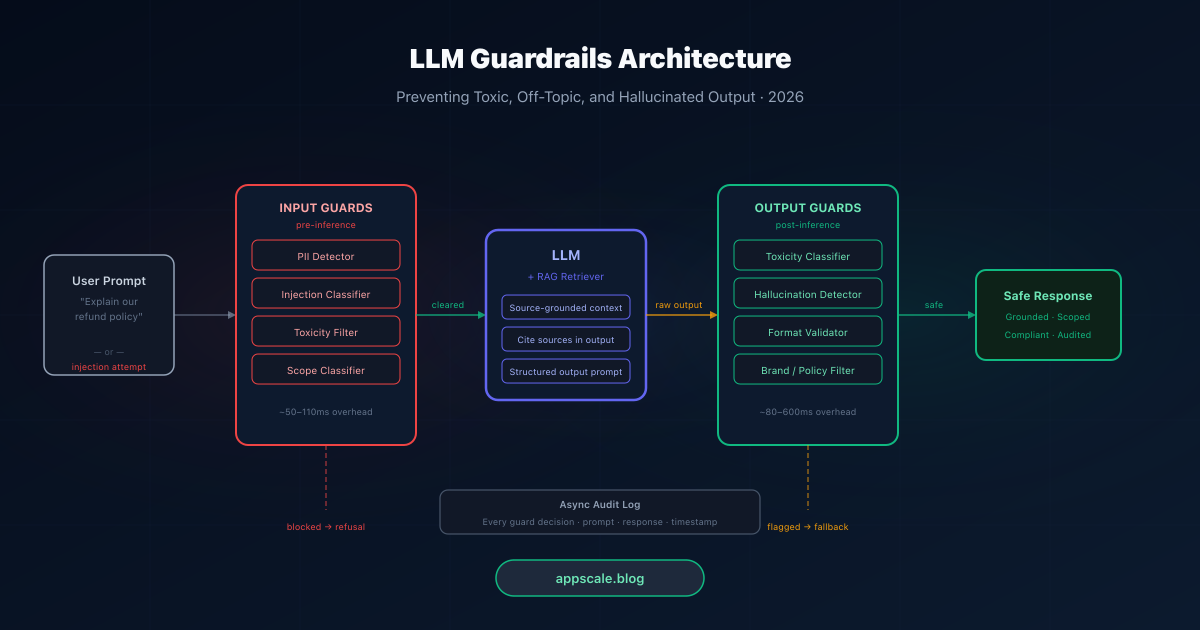
Guardrails for LLMs: Preventing Toxic, Off-Topic, and Hallucinated Output

By Satyam KumarApril 6, 202615 min read
llm guardrails ai guardrails nemo guardrails guardrails ai prompt injection hallucination detection ai safety llm safety enterprise ai responsible ai
Guardrails for LLMs: Preventing Toxic, Off-Topic, and Hallucinated Output

Frequently Asked Questions

Compartir este artículo

Twitter LinkedIn WhatsApp

Satyam Kumar

Founder & AI Architect, AppScale LLP

Arquitecto de IA y Cloud. Ayudando a equipos a construir sistemas que escalan a millones.

Comments

Leave a comment