Skip to content
Back to Blog
ai-architecture

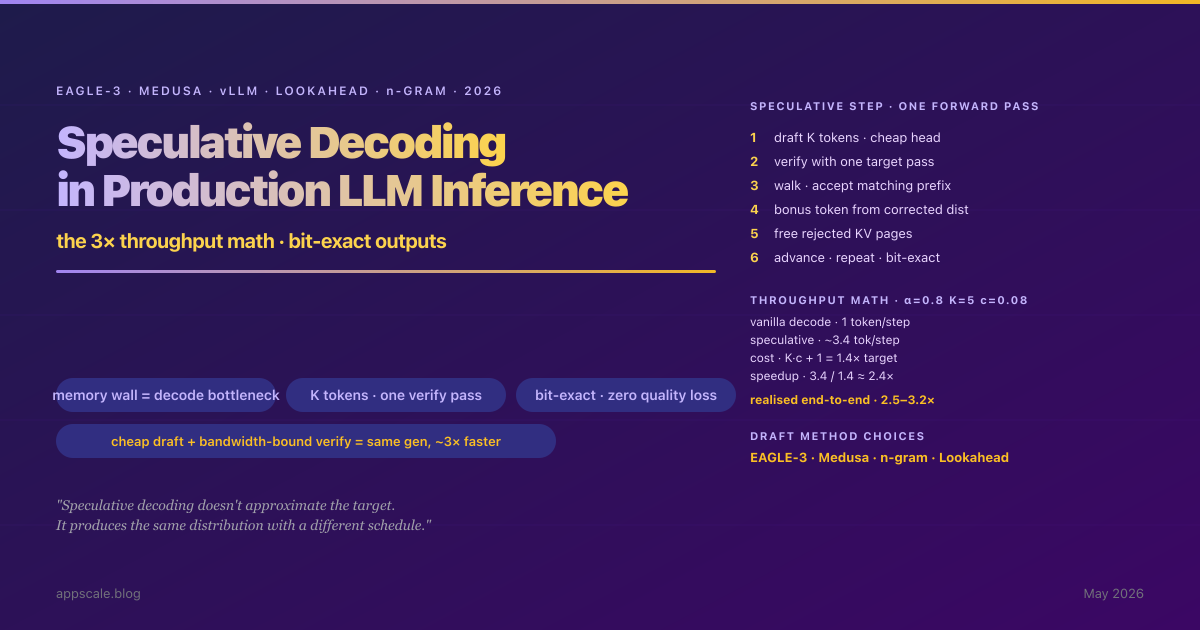
Speculative Decoding in Production LLM Inference: EAGLE-3, Medusa, vLLM, and the 3× Throughput Math (2026)

By Satyam KumarMay 20, 202634 min read
speculative decoding llm inference eagle eagle-3 medusa vllm lookahead decoding n-gram speculation kv cache paged attention inference optimization gpu serving tensorrt-llm sglang autoregressive decoding ai infrastructure production llm 2026
Speculative Decoding in Production LLM Inference: EAGLE-3, Medusa, vLLM, and the 3× Throughput Math (2026)

Frequently Asked Questions

Share this article

Twitter LinkedIn WhatsApp

Satyam Kumar

Founder & AI Architect, AppScale LLP

AI & Cloud Architect. Helping teams build systems that scale to millions.

Comments

Leave a comment