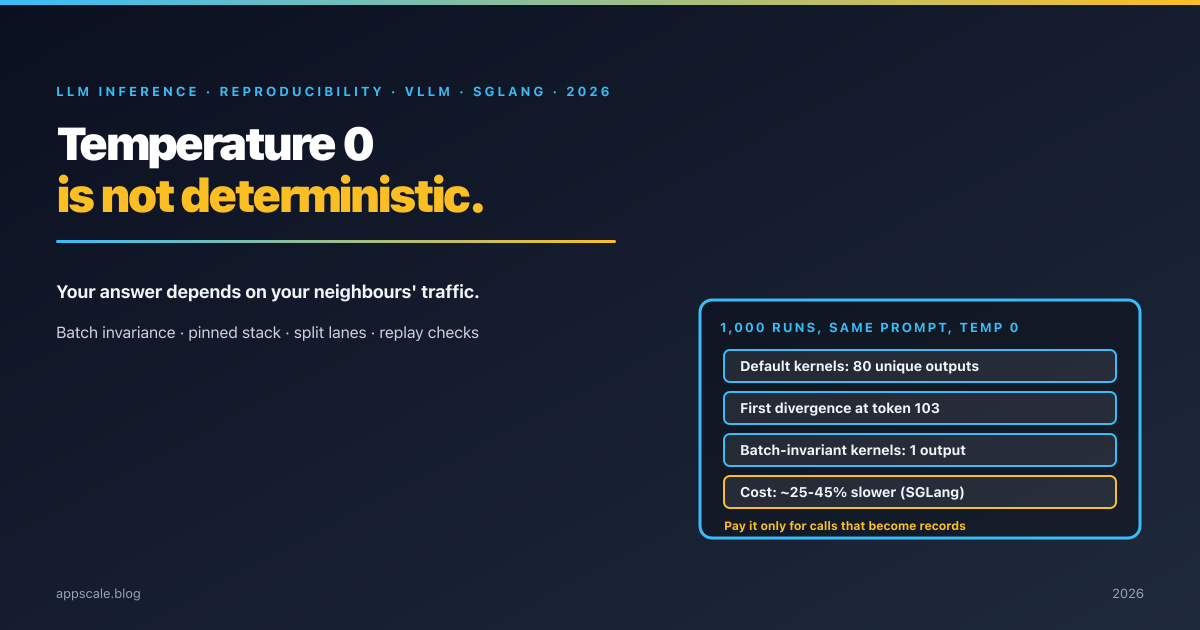
Temperature 0 Is Not Deterministic: Batch Invariance and Reproducible LLM Inference in 2026


A classification backfill through the chat endpoint turned a $400 job into $3,000 and still failed. Batch LLM inference: half the cost, resumable, built for finite jobs.
vLLM, SGLang or TensorRT-LLM? How to choose an LLM inference server in 2026 by prefix-reuse ratio and hardware commitment, not by a public benchmark.
GPUs dominate self-hosted inference cost. Quantization cuts memory 2-4x for a small accuracy hit: FP8, INT8, AWQ, GPTQ, GGUF, PTQ vs QAT, and when not to do it.
A judge scored 4.6/5 for months while users churned over wrong answers. When to use LLM-as-a-judge, when deterministic checks win, and the calibration that separates them.
Advertise and partner
Reach engineering leaders and CTOs reading about AI, mobile and cloud architecture.
Sponsored mentions and co-authored articles or technical deep-dives. Relevant products only, always disclosed.